Part 3 — Divergence and Coalescing
In Part 2 we wrote a basic kernel, launched it, and checked for errors. Now we turn to the problem of actually making it fast. To that end, we need a refined model of how the hardware operates: threads do not run one at a time, but in groups of 32 that share one instruction stream and issue their memory accesses together.
When the hardware executes 32 threads together, these threads can differ in what they want to do next. They can disagree about which instruction to run — that is divergence — or about which address to read — that is the coalescing problem. In the worst case, this will lead to the hardware serializing operations, negating the massive parallelism advantage of the GPU. Finally, we look at the profiling tools that help measure and diagnose these issues.
3.1 Single instruction, multiple threads
When a CPU runs multiple threads in parallel, each thread's instructions need to be individually fetched and decoded. Scaling this up to thousands of threads would mean that a large fraction of processing power and die area would have to be spent on these processes, leaving less resources for the actual number crunching. To shift that trade-off favourably, GPUs execute threads in groups, called warps (or wavefronts in AMDs terminology).
At any given time, every one of the 322 threads in the warp has to run the same instruction, an execution model called SIMT (Single Instruction Multiple Thread), in contrast to the MIMD (Multiple Instruction Multiple Data) model of multiple parallel CPU threads. In fact, SIMT is much closer to the SIMD (Single Instruction Multiple Data) model of vector units in CPUs, in which one instruction of a single thread is applied to many values at the same time. The figure below illustrates the different execution models:
In the SIMT model of the GPU, one instruction is issued1 for a whole warp, and its 32 lanes then execute that operation on their own registers, on their own data. An instruction retires when its result is available — for arithmetic, a few cycles later; for a load, possibly hundreds. Between issuing an instruction and being able to issue the next one that depends on it, a warp is stalled. A lot of optimization work is focused on how to minimize stalls.
This execution model leads to the following question: What if two threads within one warp want to execute different instructions?
3.2 Divergence
Consider a branch whose condition differs between lanes of the same warp:
__global__ void divergent_lanes(int n, const float* in, float* out) {
    int i = blockIdx.x * blockDim.x + threadIdx.x;
    if (i < n) {
        float v = in[i];
        // Neighbouring lanes disagree, so both paths are live in every warp.
        out[i] = (threadIdx.x & 1) ? path_a(v) : path_b(v);
    }
}
Thread 0 wants to follow path_b, thread 1 needs path_a. What the hardware does
in these cases is run both sides, but disable the threads that should not follow the currently executing path.
First, run the instructions for path_a with all odd threads enabled, then run the instructions for path_b
with all even threads enabled. This is divergence: the two halves of the warp do not run concurrently, they run in sequence.
The consequence is that, even though each thread follows only one path, the total running time is the sum of both paths. The same kernel, split so that whole warps agree, does the same arithmetic:
__global__ void divergent_warps(int n, const float* in, float* out) {
    int i = blockIdx.x * blockDim.x + threadIdx.x;
    if (i < n) {
        float v = in[i];
        // The condition is constant across a warp, so each warp takes one path.
        out[i] = ((threadIdx.x >> 5) & 1) ? path_a(v) : path_b(v);
    }
}
The condition is now uniform across each warp. Every lane of an even warp takes one path, every lane of an odd warp the other, so each warp executes one path and skips the other entirely.
The two arrangements are drawn below, each with two warps side by side, lanes running across and execution running down.
To get some real measurements, let us define path_a and path_b so that their cost is large enough to cover
the latency of the memory transfers:
constexpr int WORK = 256;

__device__ __forceinline__ float path_a(float v) {
    #pragma unroll 1
    for (int k = 0; k < WORK; ++k) v = fmaf(v, 1.0001f, 0.5f);
    return v;
}

__device__ __forceinline__ float path_b(float v) {
    #pragma unroll 1
    for (int k = 0; k < WORK; ++k) v = fmaf(v, 0.9999f, 0.25f);
    return v;
}
Timing both over 4.19 million elements:
| Kernel | Time |
|---|---|
divergent_lanes — split by lane |
0.41 ms |
divergent_warps — split by warp |
0.21 ms |
A factor of 1.97×, for a half-and-half split between two paths of equal length, almost exactly what our execution model predicts.
The factor is not always two. It is set by how much of the warp's work has to be serialized, so a switch on
threadIdx.x % 32 with 32 non-empty cases costs 32 times a single case, while an if taken by one lane in a
thousand warps costs almost nothing — the warps in which no lane takes it skip the branch outright.
The bounds guard from Part 2, if (i < n), has a condition that depends on threadIdx.x. What is the cost of this branch?
✦ Solution
The condition is false only for threads past the end of the array, and those are consecutive, so at most one warp in the entire grid has lanes on both sides of it. Every other warp evaluates the condition to the same value in all 32 lanes and simply proceeds, so the cost is limited to one comparison.
Even for the boundary warp, there is no real cost, because one of the branches terminates immediately, so there is no path_b
to execute.
Takeaway
Threads execute together in groups of 32 called a warp. Divergent branches are costly, because they require serialization.
Case StudyMandelbrot
Let's consider the task of visualizing the Mandelbrot set: for each point c of
the complex plane, iterate z <- z² + c from zero and count the steps until |z| exceeds 2.
__device__ __forceinline__ int escape(float cx, float cy, int maxit) {
    float x = 0.0f, y = 0.0f;
    int i = 0;
    while (i < maxit && x * x + y * y < 4.0f) {   // still inside radius 2?
        float t = x * x - y * y + cx;             // z <- z^2 + c
        y = 2.0f * x * y + cy;
        x = t;
        ++i;
    }
    return i;
}
The quantity of interest is the number of iterations. Color-coding the trip count gives the famous Mandelbrot image, where black indicates reaching the maximum iteration count without escaping:
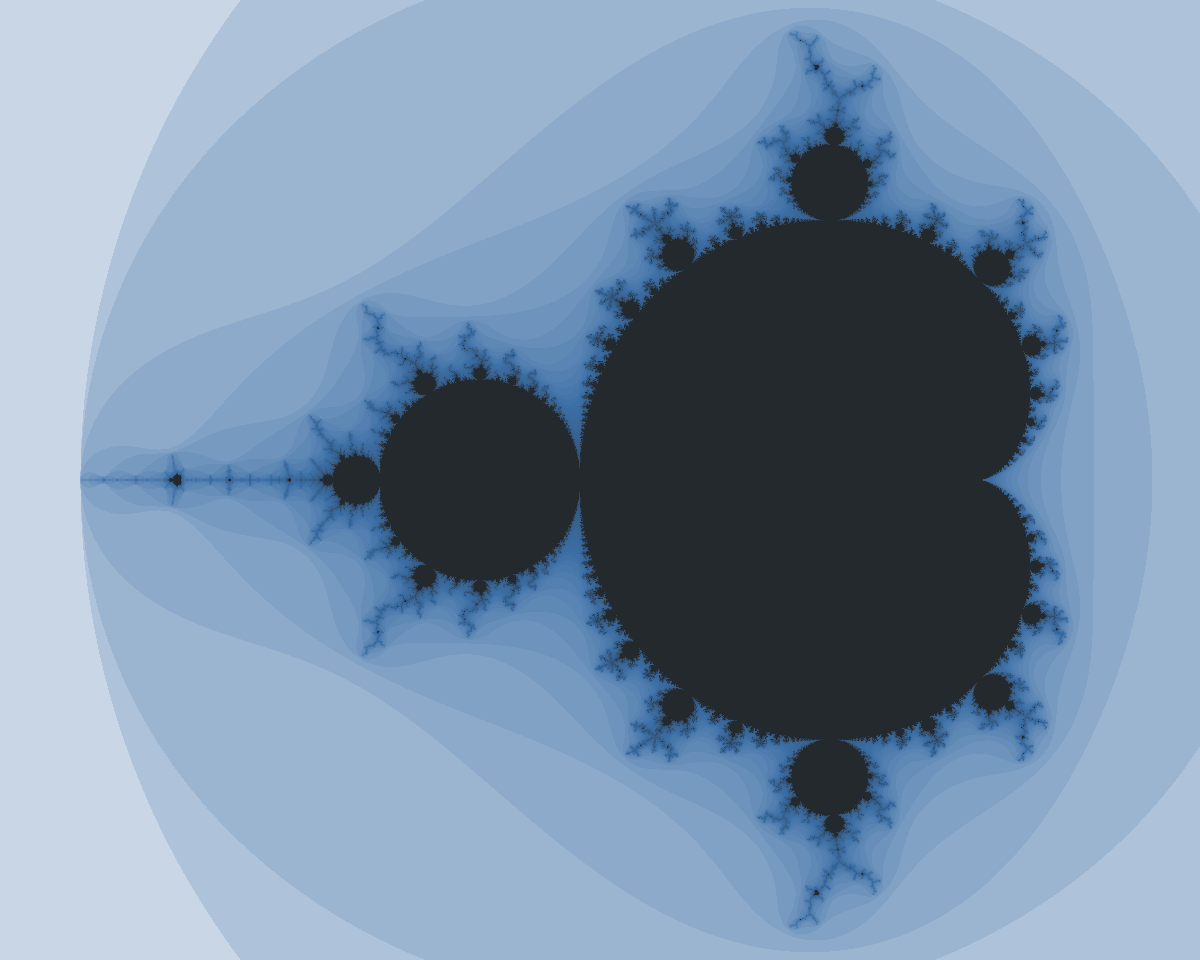
As the color represents iteration count, it also encodes how expensive it is to calculate each pixel. However, since a warp stays in the loop until its last lane leaves, a warp costs the maximum over its 32 lanes rather than their average. In the areas of the image that are largely one color, the threads in a warp agree, but in the boundary regions there will be divergence.
Let us use the straightforward thread-to-pixel mapping, where lane i takes pixel i, linearly mapped to image coordinates:
__device__ __forceinline__ int pixel_escape(int j, int W, int H, int maxit) {
    float cx = -2.2f + 3.0f * (j % W) / W;
    float cy = -1.2f + 2.4f * (j / W) / H;
    return escape(cx, cy, maxit);
}

__global__ void coherent(int W, int H, int maxit, int* out) {
    int j = blockIdx.x * blockDim.x + threadIdx.x;
    if (j < W * H)
        out[j] = pixel_escape(j, W, H, maxit);
}
Compare that against the same pixels dealt out so that a warp's lanes land all over the image. Multiplying the index by an odd constant modulo a power of two permutes it, so this computes precisely the same pixels, and the same total number of iterations:
__global__ void scattered(int W, int H, int maxit, int* out) {
    int i = blockIdx.x * blockDim.x + threadIdx.x;
    int n = W * H;
    if (i < n) {
        int j = (int)(((long long)i * 2654435761u) % n);   // a permutation of 0..n-1
        out[j] = pixel_escape(j, W, H, maxit);
    }
}
| Mapping | Time |
|---|---|
| lane i takes pixel i | 0.34 ms |
| the same pixels, permuted | 1.16 ms |
3.45× for computing the same 4.20 million pixels at the same 112.80 iterations on average, with the same number of threads.
The permuted kernel also stores to permuted addresses, so it is fair to ask how much of that is the uncoalesced write (to be discussed later in this part) rather than the divergence. Running it once more with the store put back in order gives 1.18 ms, which is no faster. Testing these kinds of probe programs can be a very useful strategy: Even though it does not produce a sensible image (the pixels are scrambled), running it told us that the bottleneck is divergence, not memory access, so if this were a real problem we'd know where to spend our efforts optimizing.
We can also ask the reverse question: Seeing that the image is highly structured, how could we organize the threads so that divergence is minimized? Currently, we use a 32×1 mapping, and if any pixel of that elongated rectangle touches a boundary, the entire warp slows down. We could try to have the warp act more localized, by mapping to an 8×4 rectangle instead:
__global__ void tiled(int W, int H, int maxit, int* out) {
    constexpr int TX = 8, TY = 4;                  // 8 * 4 = one warp
    int warp = (blockIdx.x * blockDim.x + threadIdx.x) / 32;
    int lane = threadIdx.x % 32;

    int tiles_x = W / TX;
    int x = (warp % tiles_x) * TX + lane % TX;
    int y = (warp / tiles_x) * TY + lane / TX;

    if (x < W && y < H)
        out[y * W + x] = pixel_escape(y * W + x, W, H, maxit);
}
The profiler can measure how many divergent branches we encounter during the program, and how many of the 32 lanes are active on average:
| Metric | 32×1 row | 8×4 tile | Permuted |
|---|---|---|---|
| Divergent branches | 194,720 | 128,108 | 1,238,197 |
| Active lanes per instruction | 29.18 | 30.36 | 7.72 |
| Duration | 384.4 µs | 365.5 µs | 1.38 ms |
A third of the divergent branches are gone and the average instruction gains a lane, a 4% improvement. In this specific problem, the original mapping was already fairly good.
3.3 Coalescing
As we have seen, instructions are executed in groups of 32. A similar granularity exists in the memory system: Memory transfers are generally handled in sectors, groups of 32 bytes with natural alignment, i.e., the address of the first byte in each sector is a multiple of 32. Even if only a single byte from a sector is needed, the hardware still has to transfer all 32.
When a warp executes a load, it issues one instruction carrying 32 addresses (one for each lane), one request. The hardware then serves it with as few sector transfers as it can, combining individual addresses together as much as possible.
Strided memory access
To illustrate this phenomenon, we use the following test program, which implements a strided access pattern, where
each thread accesses a four-byte float that is offset by stride from the previous one:
__global__ void strided_read(int n, int stride, const float* in, float* out) {
    int i = blockIdx.x * blockDim.x + threadIdx.x;
    if (i < n)
        out[i] = in[(size_t)i * stride];
}
Running this kernel for 16.78 million elements, the total amount of useful data transferred is independent of the stride. With stride 1, each transferred 32-byte sector delivers its 8 floats, but as the stride increases, more and more data is transferred in vain, until we reach a single useful float per sector:
Measuring the time it takes to run each setting, we can calculate the effective bandwidth at which useful data is transferred:
| Stride | Lanes per sector | Useful bandwidth | Relative |
|---|---|---|---|
| 1 float | 8 | 561.40 GB/s | 1× |
| 2 floats | 4 | 385.70 GB/s | 0.69× |
| 4 floats | 2 | 238.10 GB/s | 0.42× |
| 8 floats | 1 | 133.60 GB/s | 0.24× |
| 16 floats | 1 | 135.50 GB/s | 0.24× |
| 32 floats | 1 | 135.20 GB/s | 0.24× |
Are these numbers in agreement with the predictions we would make based on sector traffic?
✦ Solution
Yes.
The kernel combines both read and write traffic, 64 MiB in and 64 MiB out.
By construction, write traffic is always contiguous, so for writing we always move exactly 64 MiB.
When the stride is 1, reading also moves 64 MiB, but when the stride is two, it moves 2 × 64 = 128 MiB,
for a total of 192 MiB. The expected slowdown thus would be 128/192 = 0.67, almost exactly the measured effect.
For stride 4 we get 128/320 = 0.4. From stride 8 on, each lane already reads a whole sector, so the read traffic
stops growing.
Caches and cachelines
So far, we have considered the spatial aspect of memory access, where we want locality in the sense of nearby threads (within a warp) accessing nearby addresses. In addition, due to the existence of caches, there is also the aspect of temporal locality. The first time any byte within a sector is requested, the entire sector is fetched from DRAM. On its way into the cores, all bytes of the sector get written into the device's level 2 (L2) cache, and then into the requesting SM's cache (L1 cache).
We can modify the kernel above to demonstrate this behaviour. Let's make each thread consume eight values, in three different layouts.
a) the threads in a warp read neighbouring addresses (i.e., in[offset + threadIdx.x]),
and the loop increases the offset by 32 elements:
__global__ void warp_strided(int threads, const float* in, float* out) {
    int tid = blockIdx.x * blockDim.x + threadIdx.x;
    if (tid >= threads) return;

    size_t base = (size_t)(tid / WARP) * WARP * PER_THREAD;   // the warp's block
    int    lane = tid % WARP;

    float sum = 0.f;
    for (int k = 0; k < PER_THREAD; ++k)
        sum += in[base + (size_t)k * WARP + lane];

    out[tid] = sum;
}
b) thread-contiguous, so that each thread holds a run of eight and neighbouring lanes are 32 bytes apart:
__global__ void thread_contiguous(int threads, const float* in, float* out) {
    int tid = blockIdx.x * blockDim.x + threadIdx.x;
    if (tid >= threads) return;

    size_t base = (size_t)tid * PER_THREAD;

    float sum = 0.f;
    for (int k = 0; k < PER_THREAD; ++k)
        sum += in[base + k];

    out[tid] = sum;
}
c) we can also have the strided layout again, where only a sparse subset of input values are read:
__global__ void strided(int threads, const float* in, float* out) {
    int tid = blockIdx.x * blockDim.x + threadIdx.x;
    if (tid >= threads) return;

    float sum = 0.f;
    for (int k = 0; k < PER_THREAD; ++k)
        sum += in[((size_t)k * threads + tid) * PER_THREAD];   // stride 8 floats

    out[tid] = sum;
}
Each kernel loads the same 256 MiB of useful data. Only a) makes use of its transferred sectors efficiently, b) and c) fetch 8× as many sectors. But crucially, in the case of b) the seven additional requests can all be served directly from L1 cache. For a memory-bound kernel like this, which spends most of its time waiting for DRAM, those extra requests cost nothing: b) moves exactly as many bytes across the bus as a) does, and takes exactly as long.
The profiler shows where the difference went:
| Metric | Warp-strided | Thread-contiguous | Strided |
|---|---|---|---|
| Load instructions | 2,097,152 | 2,097,152 | 2,097,152 |
| Load sectors | 8,388,608 | 67,108,864 | 67,108,864 |
| L1 sector hit rate | 0.00% | 86.15% | 0.00% |
| DRAM read | 256.0 MiB | 256.0 MiB | 2.0 GiB |
| DRAM throughput | 94.72% | 94.45% | 94.56% |
| Duration | 457.9 µs | 458.2 µs | 3.60 ms |
Compare the last two columns: in both, each individual access has the same bad, strided pattern, and the sector counts cannot tell them apart. But in one case seven out of eight of those accesses are served from L1 cache, so the total memory traffic to DRAM is the same as with the good access pattern.
Despite the good results here, it is important to remember that in a real kernel, the GPU might be doing more work already, and the additional latency due to ineffective L1 cache access might influence overall performance. This is particularly relevant for datacentre GPUs, which have much higher DRAM bandwidth.
Takeaway
Memory access is most efficient if it happens coalesced, that is, each warp asks for a contiguous, cache-line aligned chunk of memory.
Case StudyRGB to greyscale
Let's consider the task of converting a colour image to greyscale: each output pixel is a fixed weighted sum of
the three input channels, grey = 0.299 r + 0.587 g + 0.114 b. One thread per pixel reads three bytes, does three
multiply-adds, and writes one byte. With that little arithmetic per byte moved, the kernel can never be faster than
the memory system delivers pixels.
What is left to decide is therefore not the kernel but the image: how a pixel's three channels are laid out in memory. That choice is usually made somewhere else entirely — by the decoder, the camera, or whatever hands you the buffer — and there are two common answers. Packed 3-byte pixels, the array-of-structs (AoS):
__global__ void grayscale_packed(int n, const uchar3* rgb, unsigned char* grey) {
    int i = blockIdx.x * blockDim.x + threadIdx.x;
    if (i < n) {
        uchar3 p = rgb[i];
        grey[i]  = luma(p.x, p.y, p.z);
    }
}
And three separate channel planes, the struct-of-arrays (SoA) version:
__global__ void grayscale_planar(int n, const unsigned char* r,
                                 const unsigned char* g,
                                 const unsigned char* b,
                                 unsigned char* grey) {
    int i = blockIdx.x * blockDim.x + threadIdx.x;
    if (i < n) {
        grey[i] = luma(r[i], g[i], b[i]);
    }
}
Both do identical arithmetic on identical pixels. But as each threads needs the three channels for each pixel, in one case we are forced to a strided load, in the other we can stay fully coalesced.
| Metric | Packed | Planar |
|---|---|---|
| Load instructions | 1,572,864 | 1,572,864 |
| Load sectors | 4,718,592 | 1,572,864 |
| DRAM read | 48.0 MiB | 48.0 MiB |
| DRAM throughput | 75.40% | 73.04% |
| Duration | 117.7 µs | 124.5 µs |
The launch is 16.80 million pixels, so 524288 warps; read the load
counts in multiples of that. The planar kernel issues three loads per warp and each costs one sector: 32 lanes
reading 32 consecutive bytes, nothing wasted. The packed kernel also issues three loads per warp — uchar3 is not
a type the hardware loads in one go — but each spans 96 bytes, so each costs three sectors. Nine sectors per warp
against three: by the sector arithmetic, the packed layout is three times worse.
It is not three times slower. It is not slower at all: 125 µs against 130 µs, with the packed layout very slightly ahead. The DRAM read column says why: both move the same 48 MiB. The three loads of the packed kernel name the same three sectors, and the L1 serves the second and third from what the first brought in. The extra cost is real, but it is paid at the L1, in requests and sectors, and this kernel has L1 throughput to spare.
So splitting the image into planes — restructuring the data the whole pipeline works on, to satisfy the rule that a warp should read contiguous bytes — buys nothing here. The packed layout was never short of what that rule protects.
3.4 Profiling
Every claim in this part was backed by a measurement, and they came from two tools: a clock, and the hardware's own counters.
Timing is the cruder of the two, and the examples in this course all do it the same way: record a CUDA event before and after, synchronize on the second, and average over enough iterations to drown out the noise, after a few warm-up runs that are thrown away. The host clock cannot substitute for this, because a launch returns before the kernel starts (§2.4). The first run is not representative either — allocations are cold and the driver may still be JIT-compiling PTX — which is what the warm-up is for.
The other tool is Nsight Compute, ncu, which runs the program and reports hardware counters per
kernel launch:
ncu ./grayscale                                  # a summary of every kernel launched
ncu --set full -k grayscale_planar ./grayscale   # every section, one kernel
ncu --set full -o profile ./grayscale            # write profile.ncu-rep for the GUI
It is not a sampling profiler. It replays each kernel launch as many times as it needs to collect the counters,
which makes the wall-clock time of a profiled run meaningless and the counters exact. Metrics are per launch, so
an example that runs its kernel twenty times for timing wants to run it once under the profiler. Compiling with
-lineinfo — the same flag §2.6 recommended for the sanitizer —
lets ncu attribute counters back to source lines.
Metric names are long but systematic: the prefix is the unit the counter sits on — gpu__ for the whole device,
sm__ for an SM, smsp__ for one sub-partition, l1tex__ for the L1, dram__ for memory — and the suffix says
how it was aggregated. The metrics quoted in §3.3 read that way: l1tex__t_sectors_pipe_lsu_mem_global_op_ld.sum
is the total number of sectors the L1 was asked for by global loads.
The first question to ask of any kernel is which resource it is short of, and two metrics answer it:
gpu__dram_throughput.avg.pct_of_peak_sustained_elapsed and sm__throughput.avg.pct_of_peak_sustained_elapsed,
each a percentage of what that part of the hardware could sustain. The baseline SAXPY kernel makes the point on
two different cards:
__global__ void saxpy(int n, float alpha, const float* x, float* y) {
    int i = blockIdx.x * blockDim.x + threadIdx.x;
    if (i < n)
        y[i] = alpha * x[i] + y[i];
}
| Metric | RTX PRO 5000 | B200 |
|---|---|---|
| DRAM throughput | 94.84% | 36.15% |
| SM throughput | 17.41% | 41.13% |
| Achieved occupancy | 79.40% | 76.04% |
On the RTX PRO 5000 the answer is unambiguous: the DRAM is at the wall and the SMs are idling. Nothing about the arithmetic is worth touching; only moving fewer bytes, or moving them better, can help. On the B200 neither number is close to its ceiling, which means the kernel is limited by something other than these two capacities. The third row rules out the simplest explanation: it is the fraction of the SM's warp slots that were occupied, and at 76.04% the machine is holding most of the warps it can hold, so the kernel is not merely short of threads to run. Why a kernel with plenty of warps can still leave the hardware idle is Part 4; the rewrite that finally uses the B200's bandwidth is Part 6.
When neither throughput explains the time, the next question is what the warps were doing instead of issuing
instructions. ncu attributes every cycle a warp spent stalled to a reason, and the distribution is usually
enough to identify the bottleneck:
| Stall Reason | Count | Visualization |
|---|---|---|
| Long Scoreboard | 103 | |
| [OTHER] | 10 |
Long Scoreboard is a warp waiting on a global memory load. For both kernels, SM throughput stayed low because the arithmetic units were just waiting on memory.
3.5 Exercise — Embedding bags
Sum groups of rows from an embedding table.
Interface
void embedding_bag(int num_bags, int dim, const int* table, const int* offsets,
                   const int* indices, int* out);
tableisnum_rows x dim, row-major. The kernel never needsnum_rows.offsetsholdsnum_bags + 1entries; bagbsums the rows named byindices[offsets[b] .. offsets[b+1]). An empty bag outputs zeros.indicesmay repeat a row, within a bag or across bags.outisnum_bags x dim, row-major.
CPU reference code
for (int b = 0; b < num_bags; ++b) {
    for (int d = 0; d < dim; ++d) {
        int sum = 0;
        for (int r = offsets[b]; r < offsets[b + 1]; ++r)
            sum += table[(size_t)indices[r] * dim + d];
        out[(size_t)b * dim + d] = sum;
    }
}
Values are int, so the check against the reference is exact.
※ Background
A categorical feature is a list of row indices into an embedding table: the items a user clicked, the words in a query. Summing the rows it names turns a list of any length into one vector of fixed width, which is what the rest of the model consumes. Recommender models spend much of their time doing this, over tables far too large to cache and lists that are short and ragged.
Production tables hold floats or bf16 rather than ints. The widths and the access pattern are the same.
Hints
※ Two loops, one thread index
The loop nest has two loops you could parallelize over, bags and dimensions, and threadIdx.x runs along only
one of them. Both choices are correct.
※ Look at what a warp asks for
Take 32 neighbouring lanes and write down the addresses they read on one iteration of the innermost loop. Do it for both choices.
※ Lengths differ
Bags are not all the same length. Which mapping puts lanes with different trip counts in the same warp?
AdvancedSIMD and SIMT
From the issue bus down, the two right-hand columns of the figure in §3.1 are the same picture: one fetch and decode, one instruction, many lanes. What differs is how the program is written, and what happens when lanes disagree.
A SIMD program names the vector explicitly — zmm0, v0 — with the element count part of the instruction, and a
conditional between elements has to be computed both ways and blended. A SIMT program is written as an ordinary
scalar thread, and the grouping into warps is the hardware's business. Masking used to be a second difference and
largely is not any more: classical SSE had none, but AVX-512 added mask registers and SVE was designed around
predicates, so a modern vector instruction can also say which elements keep the result. That is predication.
Control flow is the difference that remains. A vector unit has one thread of control, so masking is the only way to let elements disagree. A warp has real branches, and hardware that tracks where lanes that took different ones rejoin, so its compiler can skip a side no lane wanted instead of issuing it. Divergence (§3.2) is the case where there is nothing to skip, because some lane wanted each side.
The same split shows up in memory: a vector load names one address and a width, a warp's load names 32 addresses that need have nothing to do with each other. That is why §3.3 was a section about addresses rather than about widths.
-
Instructions are fetched and decoded before they can be issued. Neither is a bottleneck in typical GPU code, so we leave them out here. ↩
-
Other vendors chose differently, which is worth knowing when reading their code or porting to it. AMD calls the group a wavefront: 64 lanes wide on CDNA, and selectable between 32 and 64 on RDNA. Intel calls it a sub-group and lets the compiler pick between 8, 16, and 32. Portable code therefore takes the width as a parameter, and CUDA code that wants to be explicit about the assumption can read
warpSize. ↩